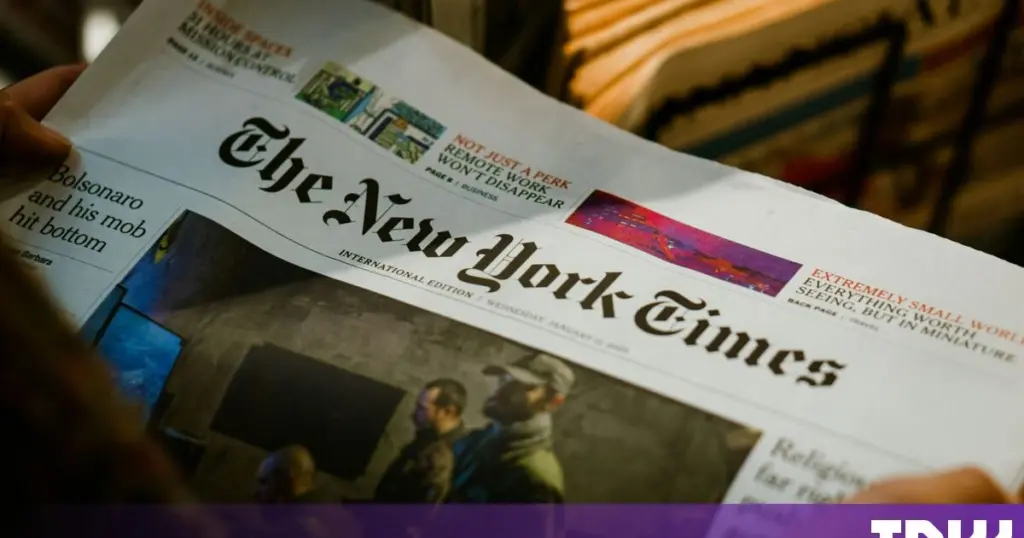
- The New York Times and three other major US publications have filed lawsuits against Brave Software, alleging unlawful content scraping.
- Brave is accused of bypassing publisher paywalls and selling access to copyrighted journalism to AI companies for training purposes.
- The lawsuits claim Brave has generated over $100 million by reselling publishers’ work without consent or compensation.
Major Publishers File Lawsuits Against Brave Software
The New York Times, along with the publishers of the New York Daily News, the Chicago Tribune, and the Orlando Sentinel, has filed separate lawsuits against Brave Software, the company behind the Brave web browser. The cases, brought in federal court, accuse Brave of unlawfully scraping their journalism, bypassing paywalls, and subsequently selling access to this content to artificial intelligence companies.
Allegations of Unlawful Content Distribution to AI Firms
The publishers contend that Brave not only scrapes their copyrighted material but also distributes it to its own users and sells it to prominent AI companies such as Anthropic, Perplexity, Mistral, xAI, and Cohere. The New York Times’ complaint explicitly states that “Brave is the supplier, dealer, and distributor of stolen copyrighted content for its own users and many of the most prominent GenAI companies.”
According to the lawsuits, AI companies reportedly pay Brave to provide them with real-time online content from the Brave search index. This content is then utilized to train their AI models and respond to specific user queries. Brave’s own website for its Search API notes that it is “used by some of the biggest names in AI, including Cohere, Mistral, Perplexity, and You.com.”
Financial Claims and Demands
Citing third-party revenue estimates, The New York Times lawsuit alleges that Brave “has made more than $100 million by copying and reselling publishers’ work without consent or permission,” while “publishers have received nothing.” The plaintiffs are demanding that Brave cease its paywall-blocking functionalities and terminate its agreements with AI firms involving their content.
This legal action highlights the increasing tension between content creators and AI companies regarding the use of copyrighted material for model training. This follows broader industry discussions, such as OpenAI’s initiatives like the Grid Protectors Program, aimed at mitigating the environmental impact of AI’s growing energy demands.
This lawsuit could set a significant precedent for content rights in the age of artificial intelligence. A favorable ruling for the publishers could fundamentally alter how AI companies source training data and impact the business models of browsers that offer paywall bypass features. For users, this might lead to changes in content accessibility through privacy-focused browsers and potentially increase the cost of accessing high-quality journalism.
This litigation against Brave Software highlights a critical inflection point in intellectual property rights within the AI ecosystem. The alleged monetization of scraped, paywalled content for AI model training, particularly the reported $100 million in revenue, underscores a significant challenge to established content licensing frameworks. A ruling favoring the publishers could fundamentally reshape data acquisition strategies for generative AI and impose stringent compliance requirements on aggregators, potentially impacting the entire value chain from data providers to AI developers.